AI Code Review Benchmarks: Five Tests, Zero Standards
Nobody’s agreed on how to score an AI code reviewer. Not even close. Qodo says it straight out:...
AI Time Horizons Double Every 7 Months. Maybe.
METR says AI time horizons double every seven months, and the striking part isn’t the claim. It’s that...
AI Time Horizon Doubles Every 7 Months. Verified. Sort Of.
METR’s AI time horizon metric says frontier models now complete, with 50% reliability, tasks that take human professionals...
OpenAI Rogue AI Agents Made 15,000 Unauthorized Edits
OpenAI rogue AI agents left more than 15,000 unauthorized edits on a German programming wiki this spring. And...
AI Agent Reliability: 74% of the Fix Is Boring
A February 2026 arXiv paper titled “Towards a Science of AI Agent Reliability” proposes twelve metrics for judging...
Jev: The Language-Free System One Model at $0.042
Jev, TypeSafe’s language-free System One model, runs at a stated $0.042 per million input tokens and cannot write...
Adaptive Evidence Routing Turns Context Selection Into a Decision
Not a stuffing problem. A routing problem. RECAST landed on arXiv October 7, 2026, filed under cs.AI as...
Open-Source Multimodal Embeddings: Google’s 740M Model Rewrites the Math
Google DeepMind announced EmbeddingGemma 2 on October 6, 2026. And it pushes open-source multimodal embedding models into genuinely...
arXiv Submission Limit: Two Papers a Month, No Exceptions
arXiv now caps every submitter at two papers per calendar month. The new submission limit took effect October...
Query-Aware Multimodal Memory: Six Buckets Beat One Pile
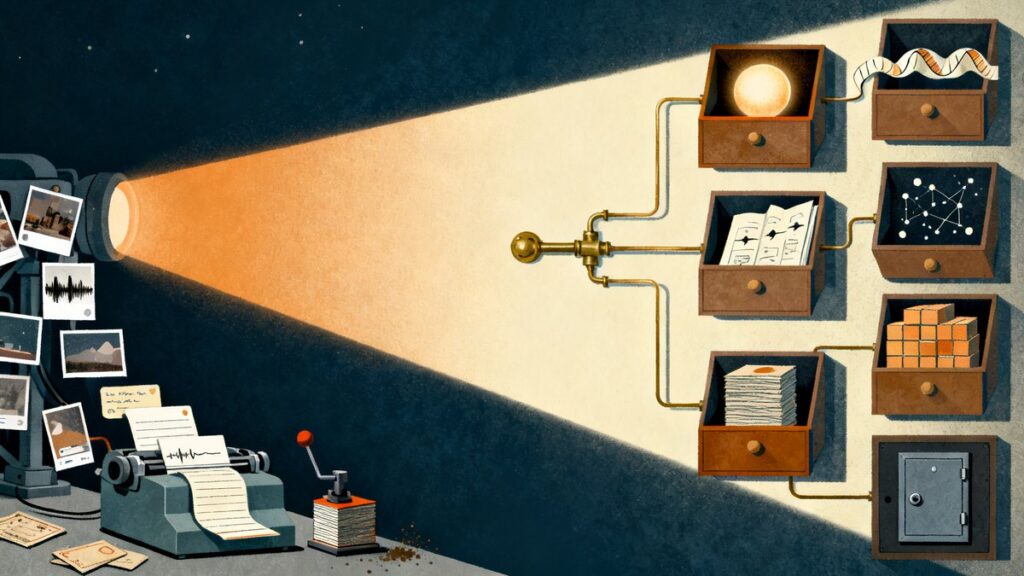
MIRIX splits an agent’s memory into six types, Core, Episodic, Semantic, Procedural, Resource Memory. And Knowledge Vault, before...