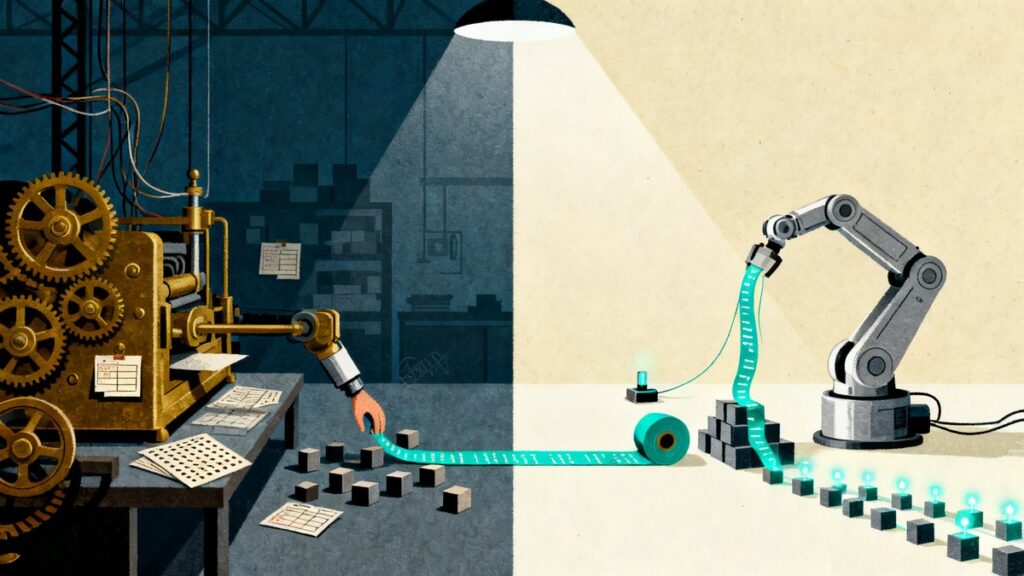
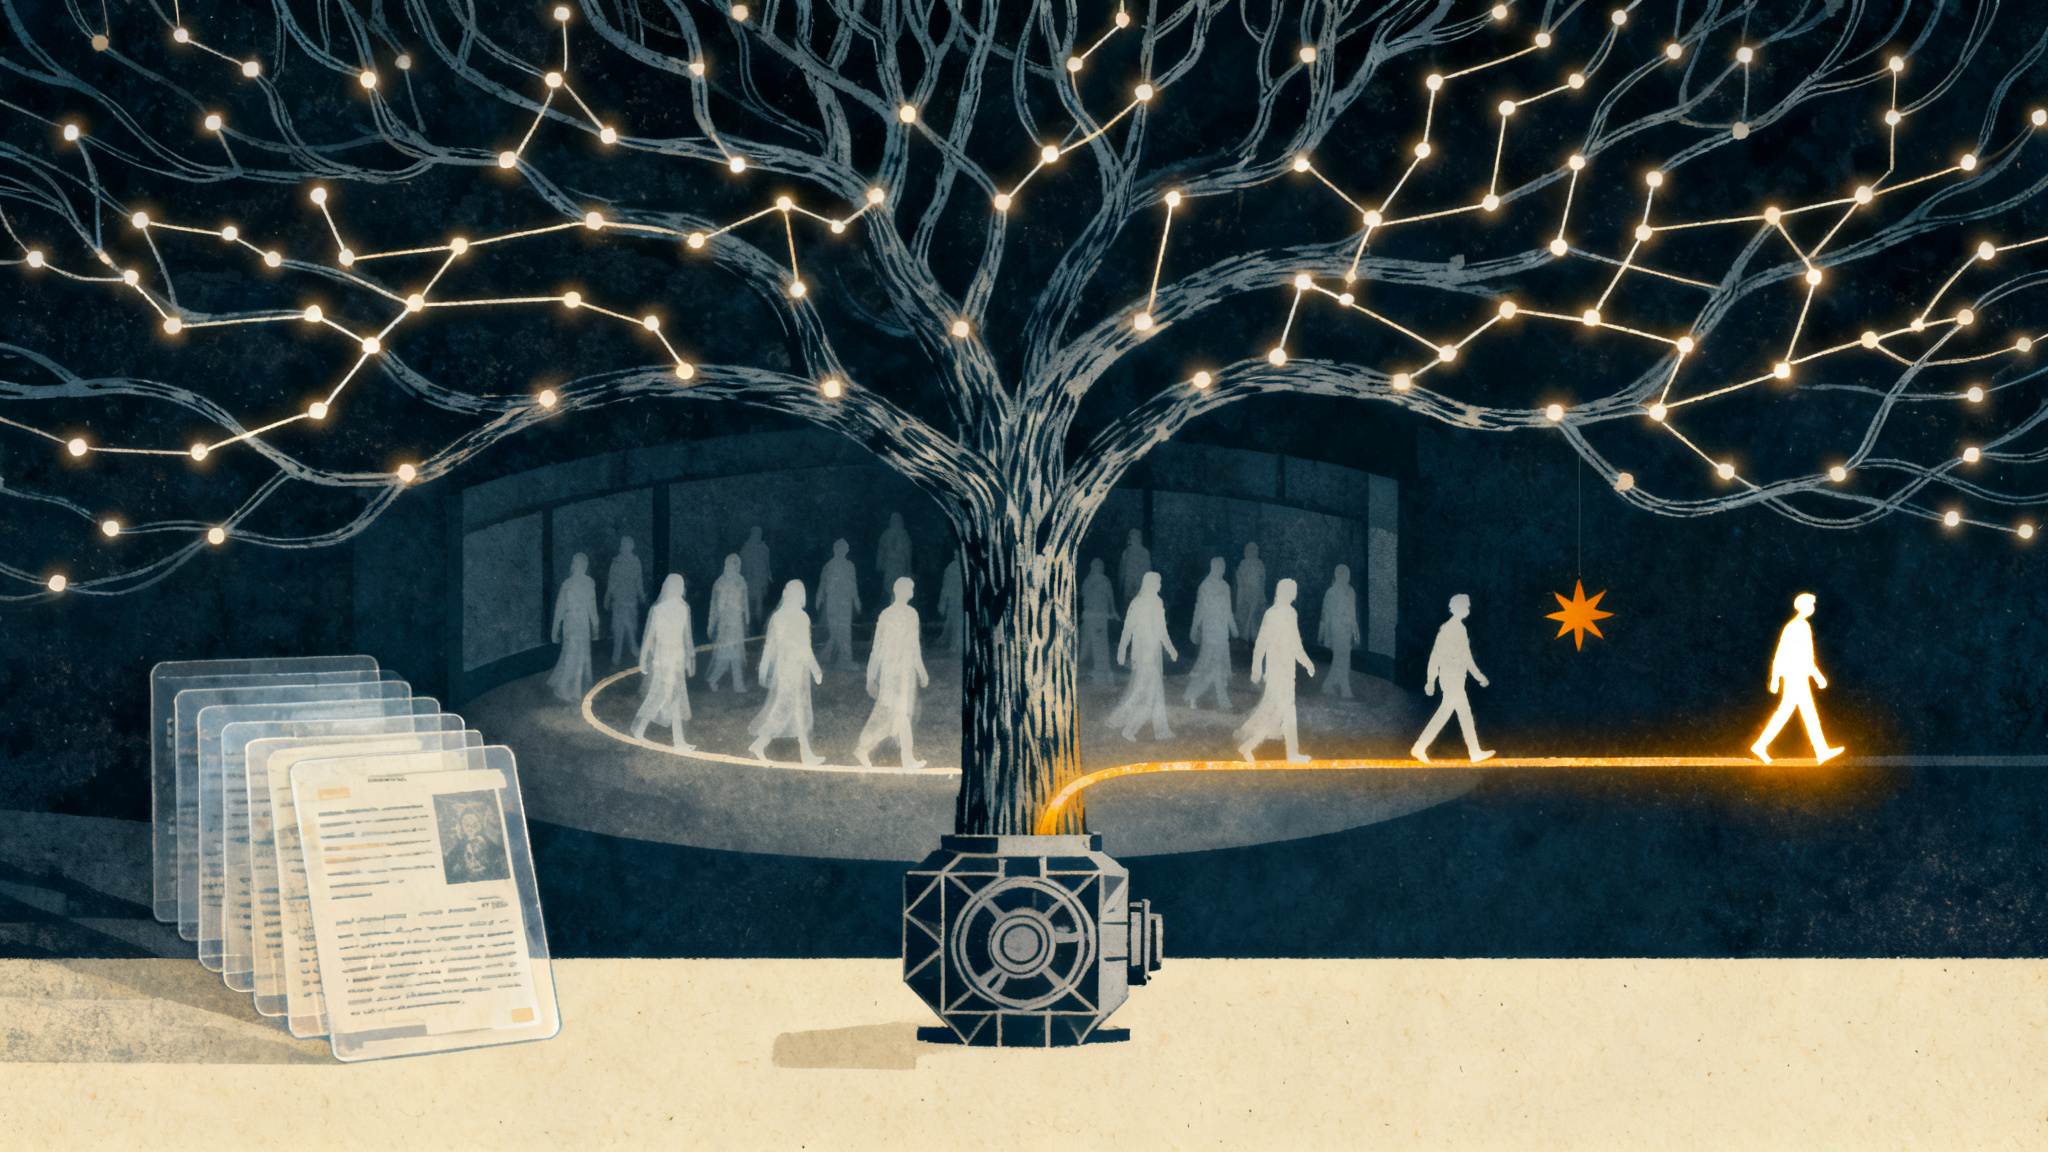
Google DeepMind’s Dream-RSI claims 162x fewer discovery-agent calls, and the trick is not a smarter model. It’s cheaper practice. A VentureBeat report credits the framework with cutting discovery-agent calls by up to 162 times versus a baseline called SimpleTES, not by making the underlying model better. But by making its search cheaper to rehearse.
Dream-RSI is laid out in the paper “Dream-RSI: Recursive Self-Improvement through Evolving Worlds” (arXiv:2609.14858, submitted September 14, 2026, with 17 authors led by first author Tong Zheng).
It is a framework for recursively self-improving exploration in coding agents. The agent’s past discovery attempts get cached and reused as a simulator. So new exploration strategies are scored against recorded history, offline, before anyone pays for a live run. The model’s weights never change. The search policy does, and that distinction is the entire story.
What Dream-RSI Actually Does
The loop has four stages: online exploration, replay-simulator construction, policy improvement, and redeployment. The agent explores for real, everything it tries gets recorded, and that history becomes raw material instead of exhaust.
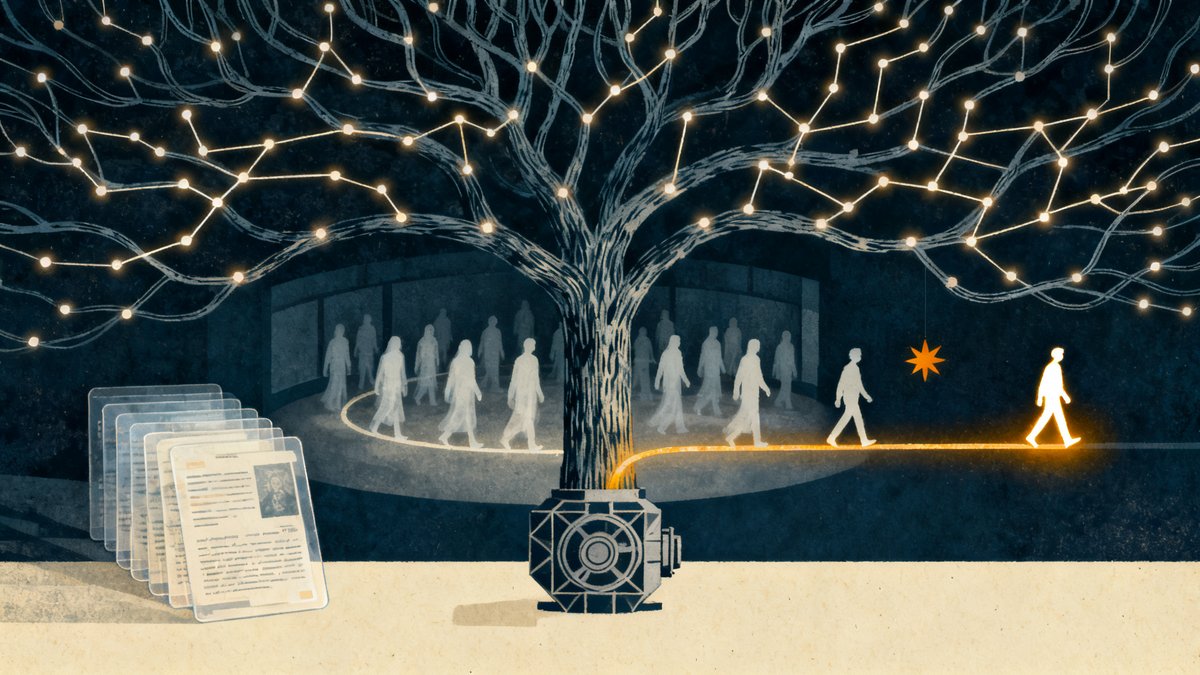
The framework stores the discovery process as a tree. A daily.dev writeup describes the cache as the agent’s code, scores. And crash outcomes, held in memory and reused as a simulator. Then comes the part the paper calls “dreaming”: an orchestration layer tests many candidate exploration policies against that replay simulator, getting fast feedback without re-running the real, expensive coding agent for each candidate.
The paper’s own phrase for this is “immediate, low-cost off-policy feedback”.
The best-performing policy gets redeployed online, where it drives the next round of real discovery.
Those new runs produce new traces, which expand the simulator pool, which makes the next round of dreaming more accurate. It is a genuine feedback loop. But notice what is inside it: the thing improving is the search policy. And the thing generating new ground truth is still the same fixed underlying agent.
The 162x Number Deserves an Asterisk
I want to be precise about what is actually verified here. Because the headline number is doing a lot of work. The 162x figure comes from a single VentureBeat report, phrased as “up to 162x fewer agent calls than SimpleTES.” Two words in that sentence deserve your suspicion.
“Up to” means a best case, not a typical case. And SimpleTES is the baseline. But nothing in the material I reviewed establishes how strong or weak that baseline actually is. A 162x improvement against a mediocre baseline is a rounding error against a good one. We do not know yet.
There is one more detail that tempers my enthusiasm. The public repository‘s own status table still listed the arXiv posting as “In progress” in the README. This is fresh research, and nobody outside the original teams has replicated the numbers. When I see a framework marketed on a single-sourced multiplier days after release, my default is to file it under “interesting” rather than “true.” That is not cynicism. That is just the base rate talking.
Is It Really Recursive Self-Improvement?
This is where the naming gets slippery, and it matters. The daily.dev discussion asks whether Dream-RSI meets I. J. Good’s original 1965 definition of recursive self-improvement. And answers no, given that the underlying model doing the improving does not itself get smarter each round. The weights are fixed. What compounds is the search strategy wrapped around them.
My take: that critique is technically right and practically beside the point. Recursive improvement of a process is still recursive improvement, and process is where most of the money lives. Think of a dev team that gets its CI pipeline down from an hour to four minutes. The engineers did not get smarter. The product still ships faster, and the compounding is real every single day afterward.
But you should resist the marketing frame, as “recursive self-improvement” invites visions of a model rewriting itself.
Dream-RSI is more honest than that and, frankly, more useful.
It improves the exploration layer. And as coverage of the paper puts it, the agent gets better at searching, not at reasoning, not at coding, not at its own weights. Anyone selling you this as a step toward autonomous model-rewriting is stretching the label past what the paper supports.
What a Small Shop Should Actually Steal From This
You cannot deploy Dream-RSI today.
It is research code with a public GitHub repository and a project site at dream-rsi.com, not a product. And the benchmarks are the researchers’ own. Fine.
The underlying idea transfers anyway, and it transfers to shops much smaller than Google DeepMind.
The insight worth keeping is that evaluation cost, not generation cost, is what kills agent budgets.
Every time your coding agent re-runs the same failed approach since it has no memory of the last failure, you are paying full price for information you already own.
Dream-RSI’s answer is to treat history as a simulator: score new strategies against what already happened instead of re-buying the answer. The cheap version of that discipline is available to you right now, with zero research code.
Keep structured logs of every agent run, inputs, outputs, pass or fail, cost.
And stop letting that data evaporate after each session.
Trace logs are an asset.
The shops that have them will adopt replay-style tuning the moment it ships inside mainstream agent tooling. And the shops that do not will start from zero. If you run agents on client work and you are not yet persisting outcomes in a form you can query later, that is the gap to close this week.
The Bottom Line
Dream-RSI is a legitimately clever frame: fix the model, improve the search, and replay history instead of re-purchasing it.
Treat the 162x claim as a hypothesis waiting for replication, not a fact. Watch the repo, read the paper when the posting finalizes, and build the habit the method depends on. Log your agent runs, keep the failures. And make your next strategy decision against recorded evidence instead of fresh API spend. If you want a hand structuring that pipeline so it pays for itself, that is exactly the work I do at Mediascout. And you can bring me your messiest agent workflow.