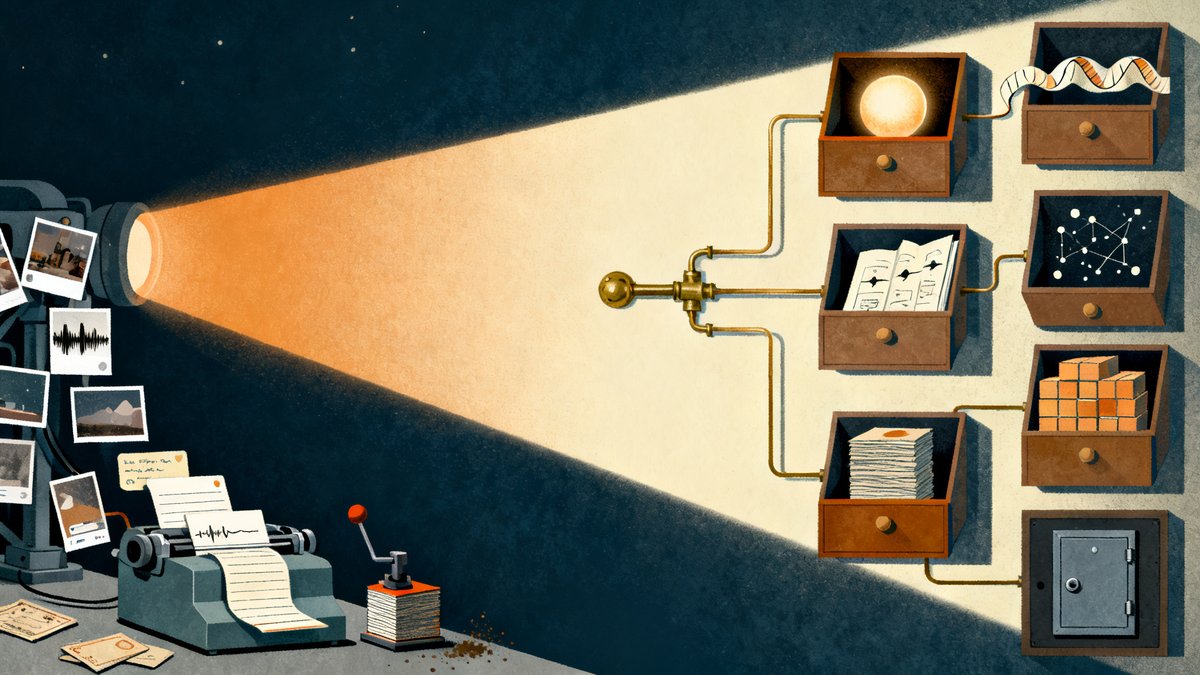
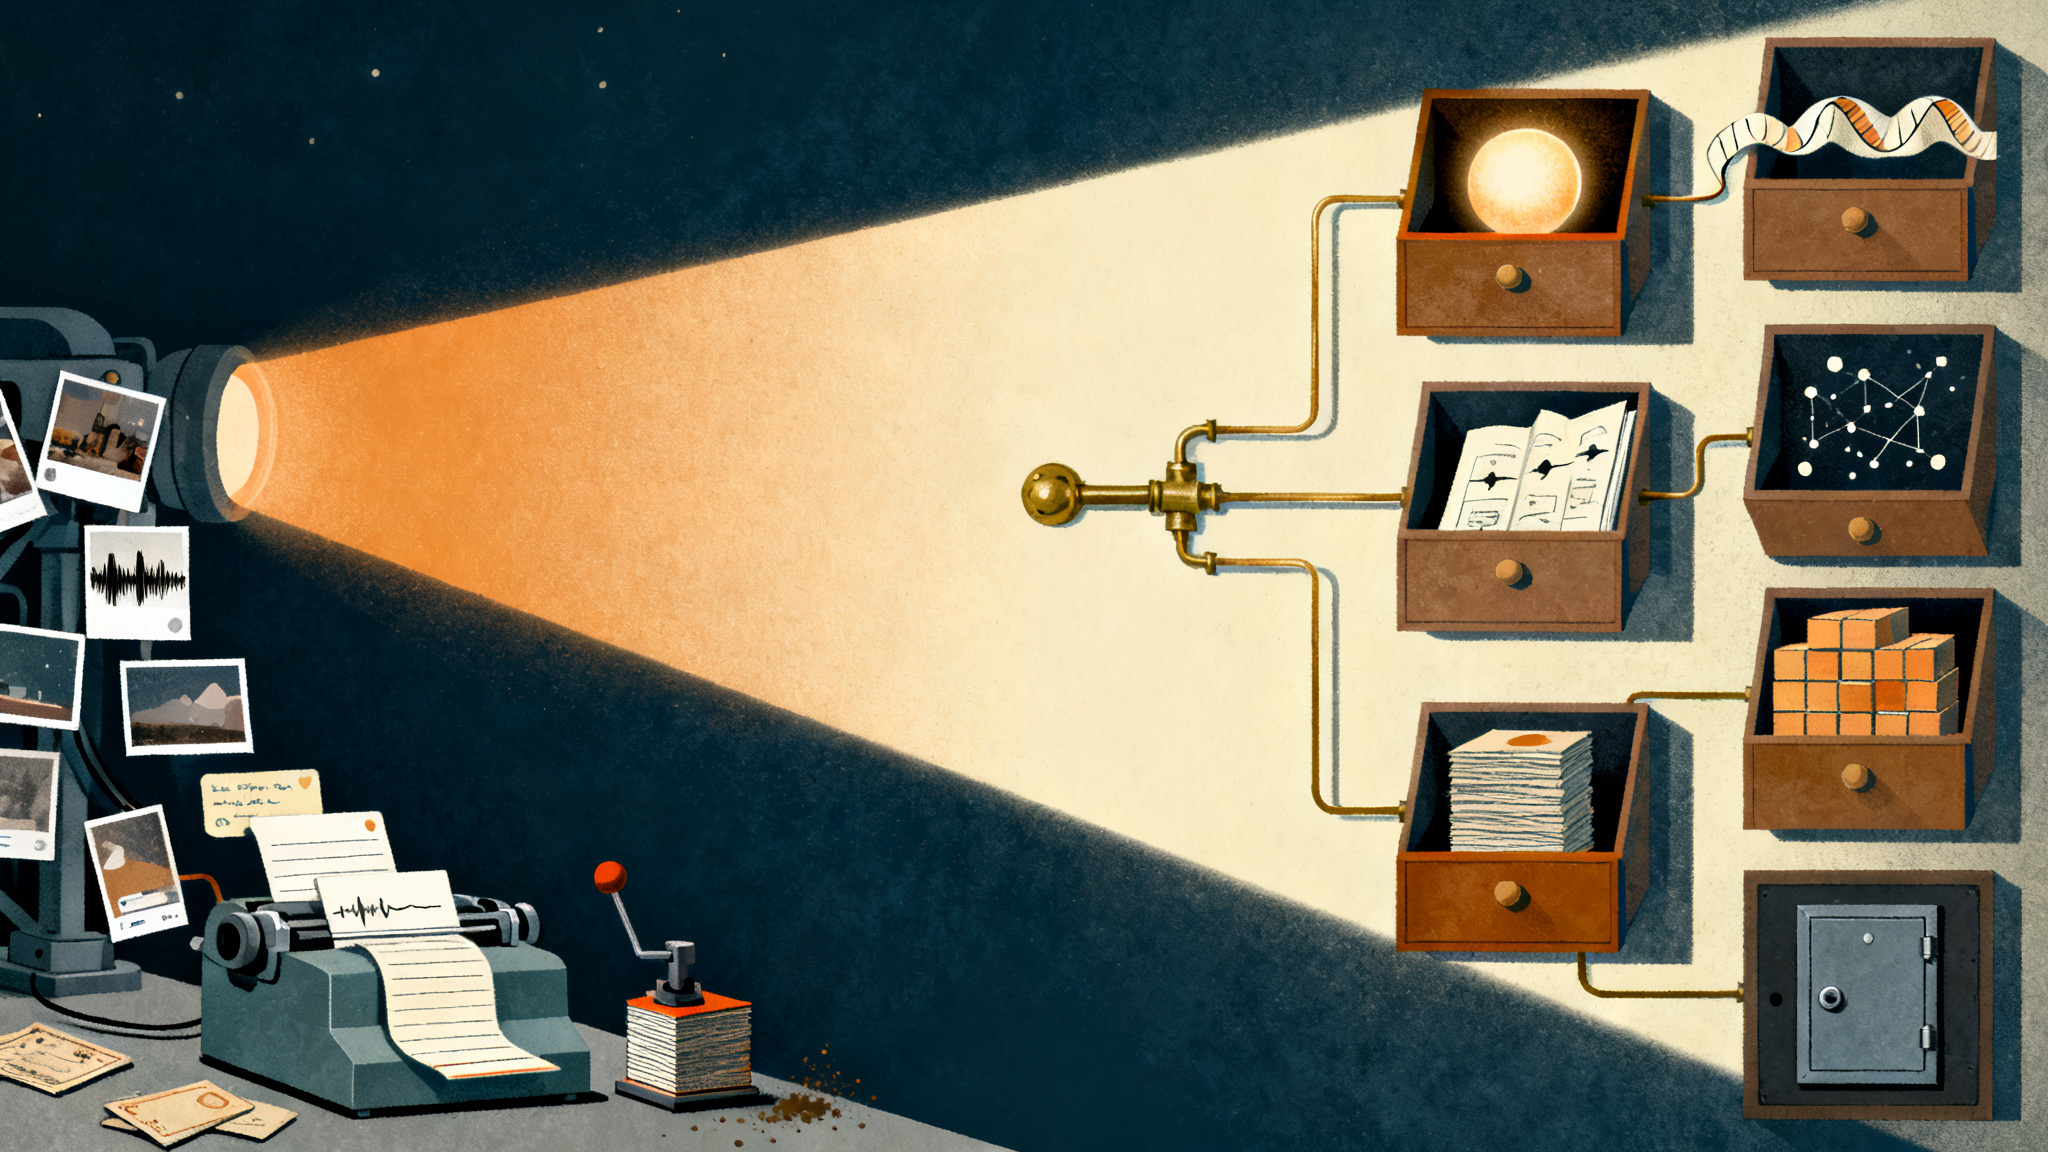
MIRIX splits an agent’s memory into six types, Core, Episodic, Semantic, Procedural, Resource Memory. And Knowledge Vault, before it answers a single question. That structure is the visible half of a bigger shift: query-aware multimodal memory curation, where an agent decides what to store, retrieve. And compress based on the question in front of it, not on a guess made when the data first arrived. The new research on arXiv keeps converging on the same move. EgoCITE reformulates your question into search queries at inference time. MemoryCPT runs rough retrieval first, then compresses candidates into a query-aware summary. The shared bet across these papers: curation that waits for the query beats summarization that doesn’t.
What Query-Aware Curation Looks Like in Practice
EgoCITE runs a three-step loop at inference time, per its paper. An LLM reformulates the user’s question into search queries. The system retrieves candidate memory entries three ways: keyword matching, vector search, or graph traversal. Then it reranks the candidates by relevance.
The reformulation step is the piece most homegrown stacks skip.
Your user’s raw question (“what did that customer send last month?”) is a terrible search query.
And firing it straight at a vector store is why retrieval feels flaky.
Handing the retrieval layer a rewritten, query-shaped version costs one cheap model call and changes what comes back.
MemoryCPT goes a step further. It performs rough retrieval before compressing candidate memories into a query-aware summary. And the paper notes its reward balances answer quality against token consumption, optimizing the cost-performance trade-off rather than raw accuracy alone. Read that twice. Memory decisions are budget decisions. A system that maximizes answer quality with no cost term will happily burn tokens summarizing everything twice.
And you get the invoice.
Multimodal Memory Starts by Turning Everything Into Text
The multimodal part sounds exotic. Implementation: almost boring. MemVerse handles arbitrary multimodal inputs by using pretrained multimodal LLMs to convert raw images, videos. And audio into textual representations, then organizes those textualized chunks alongside original text into core (user-specific), episodic (time-ordered), and semantic (relational) memory. It also keeps a lightweight language model as parametric memory and updates it through periodic supervised fine-tuning on long-term-memory contents.
MIRIX takes a wider cut, embracing visual and multimodal experiences rather than restricting memory to text, with a multi-agent framework coordinating updates and retrieval across its six memory types. MAGE goes the infrastructure route: a hypergraph-based multimodal database designed to serve as a memory engine for multi-agent systems.
Here’s my take. Textualization is unglamorous and it’s the part you can copy this week without a research budget. If your stack can’t describe a screenshot in words, it can’t remember the screenshot. And no database topology fixes that. Get the describe-then-store step right before you shop for hypergraphs.
Retrieval Is Becoming a Routing Problem
AdaMM couples data-driven structure induction with memory-aware query planning.
At inference time, a memory-aware planner decomposes queries into retrieval and analytic operations and routes each operation to the appropriate tools. Underneath, it maintains two subsystems: retrieval memory for flexible semantic access.
And analytic memory for executable analysis over recurring observations.
MIRIX makes the same point from another angle.
Its Active Retrieval mechanism requires the agent to generate a topic from the input context before answering, then uses that topic to retrieve relevant memories from each memory component, with the retrieved information fed into the system prompt.
Translated for operators: the first decision in your memory pipeline should be “what kind of question is this.” Semantic lookup, computation over recurring observations. And topic-driven recall are three different jobs. Routing all of them through one vector store treats them as the same job. And you pay for the confusion in answer quality.
The Four-Competency Test Your Memory Stack Should Pass
MemoryAgentBench identifies four core competencies for memory agents: accurate retrieval, test-time learning, long-range understanding. And selective forgetting. That list doubles as an audit checklist for anything you build or buy.
– Accurate retrieval: does it pull the right memory for the current question, not a near-miss?
– Test-time learning: does it absorb new facts mid-conversation without a rewrite?
– Long-range understanding: does it connect things said far apart in the session?
– Selective forgetting: does it drop what’s stale instead of confidently repeating it?
My read is that selective forgetting is the competency most builds skip. And it’s the one that poisons answers quietly. An agent that never forgets an outdated price or an old refund policy sounds authoritative while being wrong, which is worse than sounding dumb. Before you add more memory machinery, write four test tasks, one per competency. And run your current stack against them. Most likely you’ll find the failure before your customers do.
What This Means If You Ship Agents
You don’t need MAGE’s hypergraph or MIRIX’s six memory types on day one. Copy the sequencing instead: textualize every input so it’s describable, defer curation until the query arrives, route separate question types to other memory machinery. And put token cost inside the objective the way MemoryCPT does. For a small operation running agents over support mail, screenshots. And order history, that discipline captures most of what the elaborate systems deliver, with a fraction of the plumbing.
Audit one thing this week: what your memory pipeline writes at write time.
If it summarizes on arrival, it is discarding details your future questions will need. And that gap is exactly what this research line exists to close. If this teardown was useful, subscribe to Mediascout. Because this is the kind of build note I publish every week.