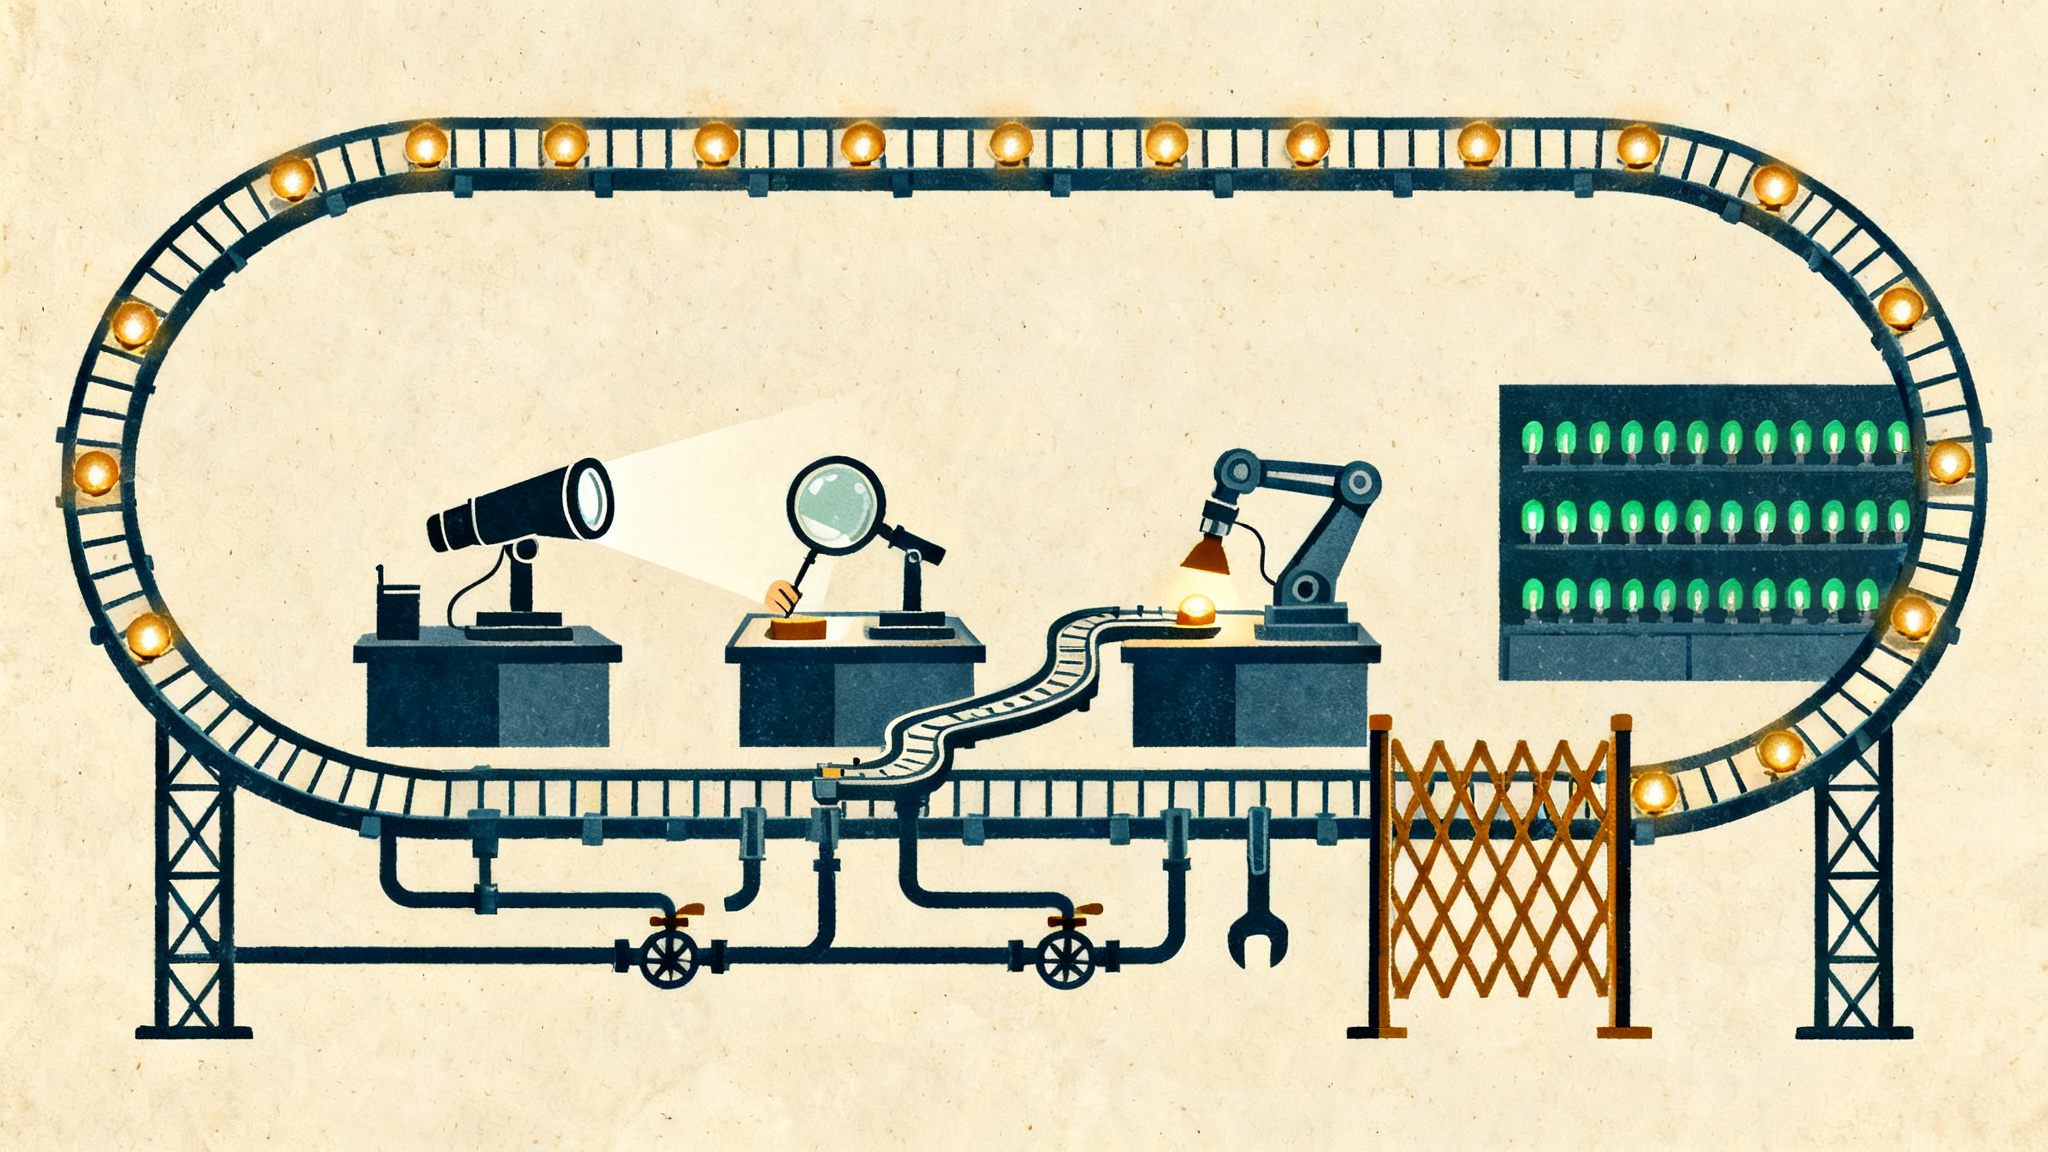
Four agent-native primitives sit underneath Copilot, Claude.
And Codex inside VS Code: the agent loop, the runtime that executes it, the tools it can call. And the modes that bound what it’s allowed to change. Microsoft’s Agent Framework docs define the agent runtime as “the runtime scaffolding that turns a language model into an agent that can perform work,” and that scaffolding, not the model ticker, decides whether a coding agent finishes real tasks or stalls at suggestions. If you run a lean operation and you’re wiring agents into how you build software, these are the four parts worth learning cold.
They’re stable in a way that model releases aren’t.
I keep watching people pick agents by benchmark scores and then lose weekends to quirks in the plumbing underneath. The primitives below are where the actual difference lives.
The Loop: Observe, Inspect, Choose, Act
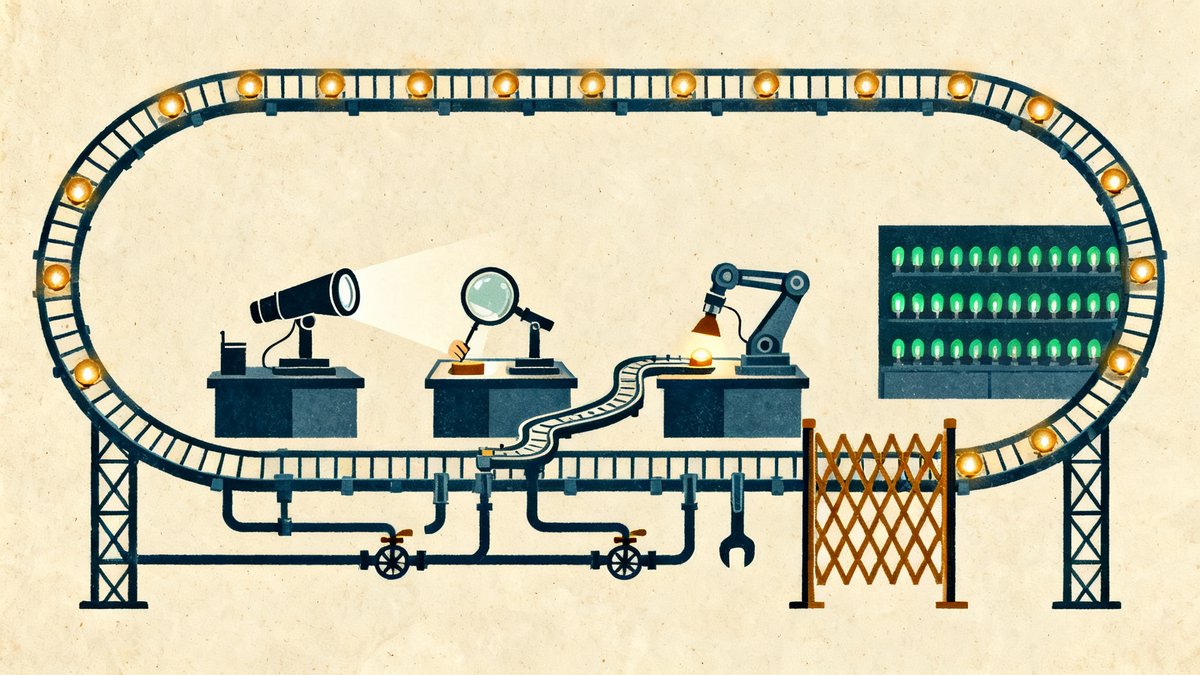
A coding agent is not a text box. VS Code’s own definition draws the line cleanly: a language model generates responses based on what’s in a prompt, while “an agent goes further by gathering context, taking actions in your development environment, evaluating the results.
And repeating these steps as needed.” That repeat is the loop. And Sebastian Raschka’s component breakdown names its four steps: observe, inspect, choose, act. Observe collects information from the environment, inspect analyzes it, choose selects the next step, and act executes it.
His framing of the division of labor is blunt and worth memorizing: the model provides the “engine,” the agent loop drives iterative problem solving. And the runtime supports provide the plumbing.
The engine gets all the press. Loop: what converts one-shot generation into finished work.
My read after pointing agents at real repositories: most agent failures are loop failures wearing a model costume. The agent acted before it inspected, or it chose a next step from a stale observation. When that happens, swapping models is an expensive non-fix.
Widening what the loop can observe before it acts is the fix.
The Agent Runtime Is the New Dependency
VS Code supports multiple agent runtimes – Copilot, Claude. And Codex among them – “each with its own tools, customizations. And workflows.” Per the docs, a runtime “manages the session, connects the language model to tools. And provides provider-specific capabilities,” while the execution environment determines where tools run and where code changes land. Microsoft’s version adds the operational detail: it “drives model and tool calls, manages conversation state and context, applies approval policies. And can keep an agent progressing through a multistep task.”
The differences between runtimes are not cosmetic. VS Code’s built-in runtime executes tasks in the extension host and iterates interactively in your current workspace. The Claude integration uses Claude project configuration and provider workflows, in your current workspace or an isolated worktree. The Codex integration supports interactive or background coding sessions.
Raschka calls the coding-specific variant a task-specific runtime for software engineering, one that manages code context, tools, execution, and iterative feedback.
That means picking a runtime is closer to picking a build tool than picking a model.
Each one carries its own config format, its own workflow assumptions. And its own session semantics, and your muscle memory compounds inside whichever you choose. For a solo operator, that switching cost is the real lock-in. A subscription cancels in a minute; the way you’ve learned to steer a runtime does not unlearn that fast.
Tools and Modes Bound the Blast Radius
MIT’s Missing Semester lesson on agentic coding puts the capability list plainly: coding agents are conversational models with tools such as reading and writing files, web search, and invoking shell commands. The VS Code tools docs make the sharper point: tools let an agent “inspect your project and check results instead of only suggesting code or commands for you to apply.” The canonical example is the whole trick in one sentence – it can read the implementation behind a failing test, make a change. And run the test to check whether the change works.
VS Code then splits capability into modes. Ask mode runs read-only tools and cannot edit files or run state-changing commands. Agent mode implements changes in your workspace and validates the result. That split is the most underrated safety primitive in the stack. Because it lets you point an agent at an unfamiliar codebase in Ask mode and get analysis with zero write risk.
You graduate to Agent mode once the plan looks right.
Defaulting to Ask mode on anything you didn’t write is the closest thing to free insurance this stack offers.
It costs one click and it has saved me from reviewing damage I didn’t authorize.
Tests Are the Contract That Makes Agents Verifiable
MIT’s lesson lands on the pattern I’d endorse hardest: “write tests (or use the coding agent to help you write tests), audit them to ensure they capture what you want. And then ask the coding agent to implement the feature.” Flip that order and you’re not delegating anymore, you’re gambling.
The same lesson names “vibe coding” – agents powerful enough that you can implement some applications without writing a single line of code yourself.
For throwaway prototypes, fine. As an operating practice for a business, it throws away the one control that works: when tests exist first, the agent’s output gets verified by a machine. And the multi-turn iteration these tools support becomes a conversation with a scoreboard.
This reframes the job for small operators.
You don’t have to write the code anymore; you have to write the specification, and the specification is executable.
Writing tests is a learnable skill in a way that debugging an agent’s unguided sprawling refactor is not.
What to Do With This
The model wars will keep resetting the leaderboard every quarter. The primitives won’t move: a loop that observes before it acts, a runtime whose workflows fit the task, tools that verify instead of suggest, modes that bound writes. And tests that turn output into pass or fail.
Run the same real task through two different runtimes in VS Code this week and compare where each one stalled. Start in Ask mode, read the plan it proposes, then switch to Agent mode with tests already in place. That habit teaches you more about agent-native development than any benchmark chart. And it’s the difference between an agent that ships and an agent that performs. The primary sources are linked throughout – the VS Code docs, MIT’s lesson. And both runtime write-ups are worth an hour of your time.