Claude Haiku 5.5 costs $0.10 per million input tokens and $0.50 per million output tokens, as long as your prompt stays under 100,000 tokens.
Anthropic announced the model on October 7, 2026 and says it costs around 75% less to run on average than Haiku 4.5, with a footnote setting the discount at 90% for requests up to 100,000 tokens and 50% for requests over that line.
Cross the line and you pay $0.50 input and $2.50 output per million tokens, five times the short-prompt rate on every line item. That tier is the real story for anyone running agents: the workhorse layer of your stack just got repriced.
And whether you actually save depends on one number most teams never measure. (Anthropic, Claude pricing docs)
The full price sheet, including the parts nobody screenshots
Here is the table I wish every launch recap included, because the footnote is where the money lives:
| | Prompts up to 100K tokens | Prompts over 100K tokens |
|—|—|—|
| Input | $0.10 / MTok | $0.50 / MTok |
| Output | $0.50 / MTok | $2.50 / MTok |
| Cache write (5-minute) | $0.125 / MTok | $0.625 / MTok |
| Cache read | $0.01 / MTok | $0.05 / MTok |
Two details the launch posts keep dropping.
One-hour cache writes run $0.20 per million tokens under 100K. And the Batch API takes 50% off input and output if your job tolerates waiting. (model overview)
The specs around the price matter too.
Haiku 5.5 carries a 1-million-token context window and a 128,000-token max output, which is generous for a model at this rate. Anthropic calls it the fastest model to date at each model’s standard speed, with the caveat that Opus models in Fast Mode still run quicker. The model string is `claude-haiku-5-5` on the Claude Platform. And it is also live on Amazon Web Services, Google Cloud, and Microsoft Azure. (Anthropic)
The cliff is keyed to prompt length, and agents live right next to it
AWS’s model card calls this what it is: “tiered long-context pricing,” triggered by prompt length. (AWS Bedrock) Every row in that table with an over-100K column jumps by exactly five times.
Input, output, cache writes, cache reads, all of it.
Here is the nuance that keeps this honest. Even the expensive tier is still 50% cheaper than Haiku 4.5 was, per Anthropic’s own footnote. So the cliff costs you five times relative to the headline price, not relative to the old model. You are never worse off than yesterday; you are just dramatically worse off than the number in the tweet you screenshotted.
The trap is structural.
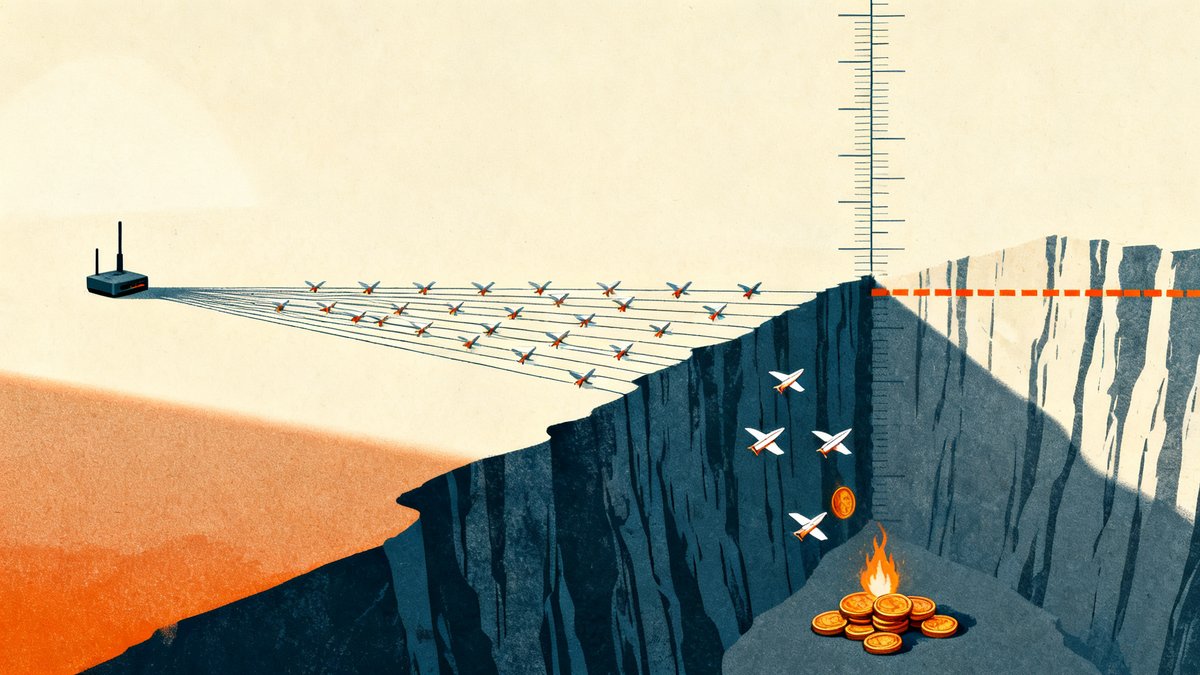
A 1M context window invites you to send long prompts. And the pricing tier punishes you for accepting the invitation. A subagent with a fat system prompt, a stack of tool definitions. And a transcript dump crosses 100K on a single call. And now every token in that request bills at the upper tier.
The capability and the price are pulling in opposite directions on purpose: this model is cheap for short calls and pointedly not cheap for reading your whole repository.
The habit that has saved me the most on API bills is unglamorous.
Before I trust any launch-day discount, I sort request logs by prompt token count. Do that once and you know which side of the line your traffic actually lives on.
This pricing is a subagent architecture in disguise
Anthropic’s own docs slot Haiku 5.5 for “high-volume, latency-sensitive tasks such as classification, extraction. And routing.” (pricing docs) Read that as a job description, since it is. This is the cheap-model-underneath pattern, finally priced like it: your expensive model makes the judgment calls. And Haiku does the thousand boring turns around them.
Route this input, classify that ticket, extract these fields, decide which specialist wakes up next.
The cache rates are the tell. Cache reads at $0.01 per million are one-tenth of an input rate that is already tiny. If your orchestrator holds a stable system prompt and fans out subagent calls that share it, reusing that prefix costs almost nothing. That is not an accident of the price sheet; it is the design intent. Anthropic priced this so that spawning more small calls is always the obvious move.
My take: “which model should I use” is the wrong question now, and this launch is the proof. The decision that matters is composition, which layer gets which job. Big models for judgment, cheap fast models for volume, and a router that knows the difference.
One warning for small operators, though.
When frontier labs start competing on the cost of the workhorse layer instead of the flagship leaderboard, the winners are people who kept their router swappable. Recouple your entire product to whichever vendor blinked this week and you get to redo it all when the next one blinks. Wrap the model choice behind one interface and treat every price as temporary.
What I’d do this week
Run the audit before you rewrite anything:
1. Pull your recent request logs and bucket every call by prompt length, under 100K versus over.
2. Price each task against the table above, both tiers, before you move it.
3. Cache every stable prefix. At $0.01 per million reads under 100K, this is the closest thing to free compute in the sheet.
4. Route anything latency-tolerant through the Batch API for the 50% discount.
5. Slim your subagent prompts. Tool definitions and transcript history are the usual suspects that quietly push calls over the line.
There is as well a subscription angle worth knowing.
Free, Pro, Max, Team. And Enterprise users can select Haiku 5.5 on Claude.ai, on web, iOS. And Android. (Anthropic) Anthropic is too handing out API credits: $100 a month for Max 5x users, $200 for Max 20x. And up to $500 pooled for Team subscribers. (Anthropic) For prototyping a subagent pattern, credits beat a metered API key. For production volume, the API table above is your real contract.
Measure first, then commit
Open your usage dashboard and sort by prompt length before you touch a single line of your router.
If your fan-out calls sit under 100K tokens, this launch is a straight discount on work you were already doing. And you should move that workload this week. If they sit over it, you just found the most valuable fact in your architecture.
And no vendor’s headline number was going to tell you.