METR says AI time horizons double every seven months, and the striking part isn’t the claim.
It’s that they published the tasks, the data. And the analysis code. And outside researchers have since used that open material to argue the famous curve rests on shakier statistics than the headline suggests.
So what is an AI time horizon?
METR defines it as the task duration, measured by how long a human expert takes, at which an AI agent is predicted to succeed with a specified reliability. Instead of asking “how smart is this model,” the metric asks “how long a task can this agent actually finish.” METR reports the point where a fitted success curve crosses 50% or 80% success probability. Here’s why you should care: if you are planning to hand real work to autonomous agents, this metric is one of the few public attempts to answer the only question that matters to an operator, which is how long a task you can trust the thing to complete. And because the whole pipeline is open, you can audit it yourself instead of taking anyone’s word for it.
The metric behind the seven-month claim
The methodology is straightforward on paper.
METR collects tasks with known human completion times, runs AI agents on them, records success or failure, then fits a logistic curve modeling success probability as a function of log2 of human minutes.
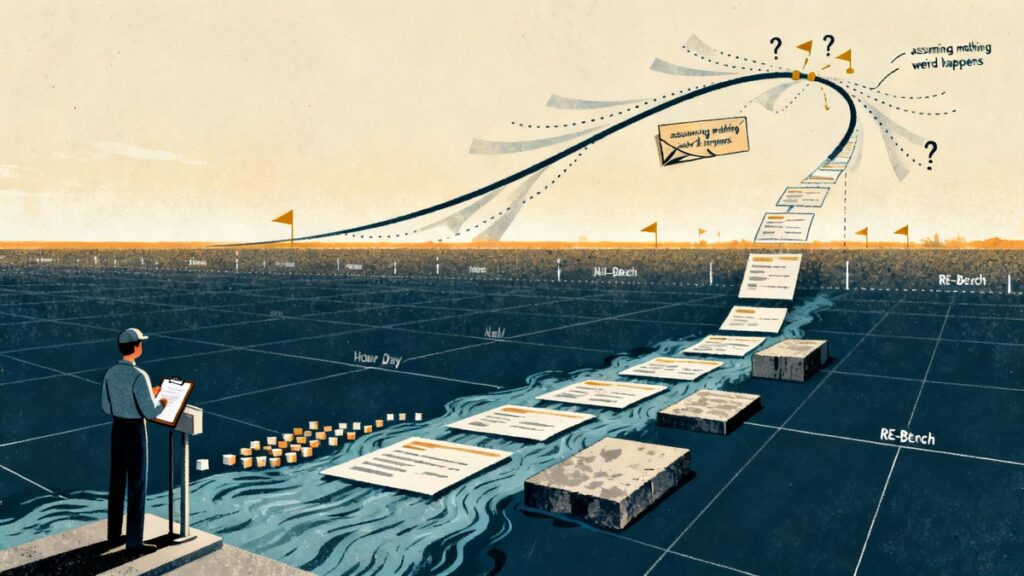
The “time horizon” is where that curve hits a chosen threshold. Their research page says this metric has been consistently exponentially increasing over the past six years, with a doubling time of around seven months.
That is the number that gets quoted everywhere. Doubling every seven months sounds inevitable, almost physical, like Moore’s Law for autonomy. I treat any number with that profile with suspicion, since a clean exponential usually means someone chose a clean model.
What TH1.1 actually changed
METR released Time Horizon 1.1, designated TH1.1, on January 29, 2026. The update grew the task suite from 170 tasks to 228 tasks and re-estimated effective time horizons for 14 models using new evaluation infrastructure. METR has open sourced its infrastructure, data, and analysis code, which is the part that matters most here.
There’s also a flag worth knowing about. METR’s original time-horizon measurements covered public language models. And in its March 19, 2025 announcement the organization said it is no longer updating those measurements with new models. So the public series everyone cites is a snapshot, not a living benchmark.
When you see the seven-month figure passed around, it is tied to a specific suite and a specific moment, not an ongoing measurement of whatever model shipped last week.
The reanalysis that pokes at the curve
This is where the open-source part pays off.
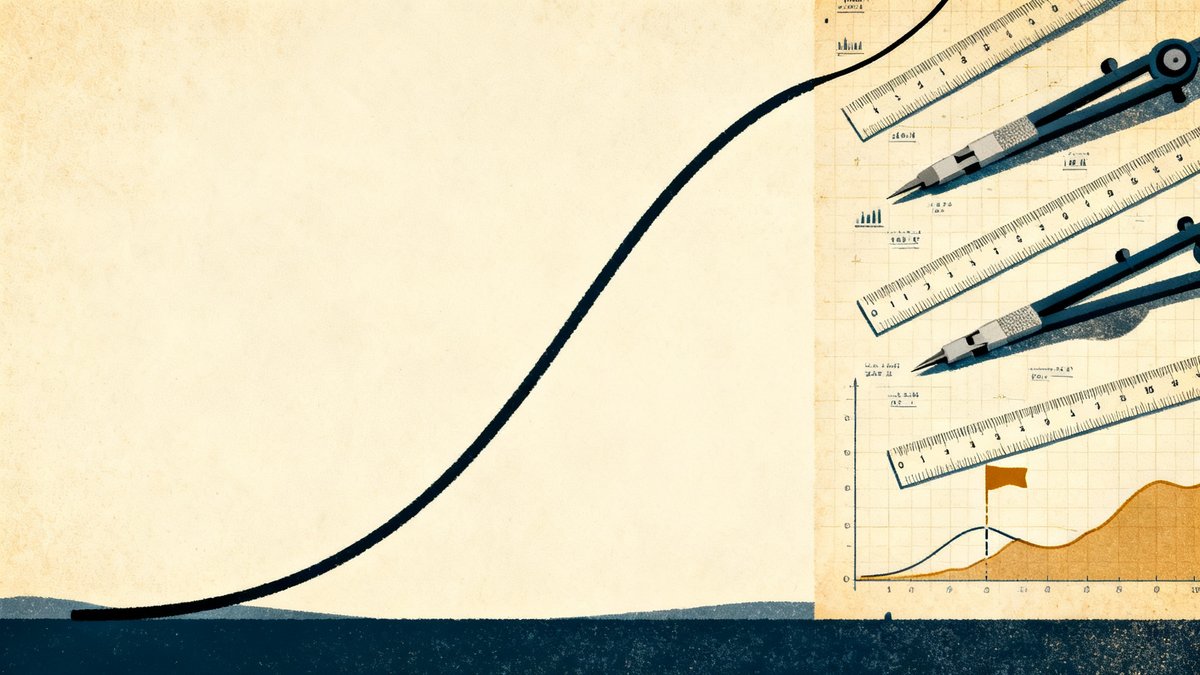
A 2026 statistical analysis recomputed time horizons using results from 228 tasks and 26 AI systems, using splines and item-response theory to relax the assumption that AI task difficulty depends linearly on the logarithm of human time.
That assumption is the spine of the original logistic fit. If it is wrong, the curve, the crossing points, and the seven-month doubling number all move.
The paper evaluated its alternative estimates with cross-validated proper scoring rules and included diagnostic plots for assessing the construct validity of time horizons. In plain terms: the authors rebuilt the ruler with better statistics and then checked whether the ruler measures anything real. That is what good evaluation looks like. And it only happened given that METR put the raw material in public.
A separate 2026 benchmark paper built a unified dataset of model performance on 170 tasks drawn from three benchmarks: Software Atomic Actions, HCAST, and RE-Bench.
Multiple groups pulling on the same open data with different methods is exactly how a metric earns trust. And exactly how it gets torn apart if it doesn’t deserve it.
What this means for a lean operator
My read: the direction is probably real. But the precision is not. “Doubling every seven months” is a fit, not a law of nature. And the 2026 reanalysis exists as smart people found the fit debatable.
If you are a small team deciding when to hand a multi-hour task to an autonomous coding agent, the actionable number is not the trend line.
It is whether a specific model, on a task shaped like yours, hits the reliability threshold you need.
That shift changes how you plan.
Don’t schedule your roadmap around the extrapolated curve. Do three cheaper things instead. First, read the definition before the number: a 50% success rate on an hour-long expert task means half the runs fail, which is a demo, not a workflow. Second, use the open repository to see how tasks get scored, since the gap between “agent completed it” and “completed it the way you would” is where budgets die.
Third, treat any headline horizon as a ceiling for planning and a floor for verification, then run your own task through the model before you bet a week on it.
Benchmark scores tell you a model can do something. A time horizon, honestly measured, tells you how long it can keep doing it before the failure rate eats you. Right now only one of those is open enough to check. And even that one is being argued over in public, which is the best outcome a buyer can ask for.
Go read METR’s methodology page and the reanalysis before your next planning session.
Your automation budget should follow verified task length, not a curve that doubles every seven months on a good day.